
Attention and Token Representations: A Worked Mathematical Walkthrough
Most people can recite the attention formula. Far fewer can compute it. That gap is worth closing, because the formula is not a wall of symbols — it is a…

Key topics
Most people can recite the attention formula. Far fewer can compute it. That gap is worth closing, because the formula is not a wall of symbols — it is a short sequence of tensor operations you can trace with a pencil.
You already know the shape of the story: text becomes tokens, tokens become embeddings, and transformers stack attention layers to turn those embeddings into predictions. What we are going to do here is shrink the problem until every number fits on one line, then walk the whole mechanism end to end. Three tokens. Two dimensions. One head. No bias terms, no dropout, one layer. By the end you should be able to say what shape every intermediate tensor has, why the scaling factor exists, and why the mask has to be applied before softmax rather than after.
Why the Formula Feels Opaque
The usual failure mode is treating Q, K, and V as three mysterious learned objects that appear from nowhere. They are not. They are three different projections of the same token vectors. Same input, three different weight matrices, three different jobs.
The real question attention answers is simple: for this token, which earlier tokens carry information I should pull in, and how much of each? Everything else — the dot products, the scaling, the softmax, the weighted sum — is machinery for answering that question with numbers.
A three-token example is not a toy dodge. It is the fastest way to see the mechanism, because every value stays checkable by hand. If you can trace three tokens, you can trace three thousand; the arithmetic just gets longer.
Notation and Shapes Before Any Numbers
Before we compute anything, let us fix the notation. Skipping this step is why the formula feels like a wall.
Let be the input matrix with shape — one row per token. In our example, and .
We have three learned projection matrices:
- with shape
- with shape
- with shape
And we compute:
Each has shape . In our example, .
Why three separate projections? If we used the raw token vectors for both queries and keys, the score for a token against itself would tend to be large relative to its scores against other tokens, because a vector's dot product with itself is its squared length. That does not make self-attention inevitable, but it biases the matching rule toward self-similarity and leaves the model with less freedom to route information elsewhere. The projections give the model learned spaces where a query can encode what a token is looking for and a key can encode what a token advertises, so the two roles can be tuned independently.
The score matrix is:
This has shape . Each row is one query scored against every key. Entry measures how much token cares about token .
The final output has shape . Each row is a context-enriched representation of one token.
Note: We are working with a single attention head, no bias terms, no dropout, and one layer. Real models add all of those. The mechanism below is the same; the bookkeeping just grows.
Knowledge check
Check your understanding
Answer this question before you continue.
A Three-Token Worked Example: Scores and Scaling
Let us set up three tokens with 2-dimensional embeddings. Keep the numbers small so every step is checkable.
Token A is , token B is , token C is .
Now define small projection matrices:
Using identity matrices keeps the arithmetic transparent. In a real model these would be learned values.
Since all three projections are the identity, :
| Token | Query | Key | Value |
|---|---|---|---|
| A | |||
| B | |||
| C |
Now compute raw dot-product scores. For token A's query against each key:
- Against A's key :
- Against B's key :
- Against C's key :
Doing this for all queries gives the raw score matrix:
Now the scaling. We divide by :
Why divide by ? As grows, dot products grow in magnitude — each additional dimension adds another term to the sum. Large scores push softmax into saturation, where one weight approaches 1.0 and the rest approach 0.0. When that happens, gradients shrink toward zero and learning stalls. The scale factor keeps the distribution in a range where softmax can still produce a useful spread of weights.
Read the scaled score matrix as a table of "how much does token care about token ." Token C, with the largest self-score, currently cares most about itself.
Knowledge check
Check your understanding
Answer this question before you continue.
Softmax and the Weighted Sum of Values
Softmax is applied row-wise, not to the whole matrix. Each row becomes a probability distribution that sums to 1.
For token A's row :
Sum:
Weights:
For token C's row :
Sum:
Weights:
The full attention weight matrix:
Each row sums to 1. Now multiply by to get the output. For token A:
For token C:
The output row is a weighted average of all value vectors. Token A's original representation was ; its output is — enriched with information routed from tokens B and C. Token C's original was ; its output is , pulled slightly toward the other tokens by the weight it placed on them.
Tip: Sanity-check your work by looking at a row that puts most weight on one key. That output should be close to that key's value vector. If it is not, you have an arithmetic slip.
Knowledge check
Check your understanding
Answer this question before you continue.
Causal Masking: Why the Future Must Stay Hidden
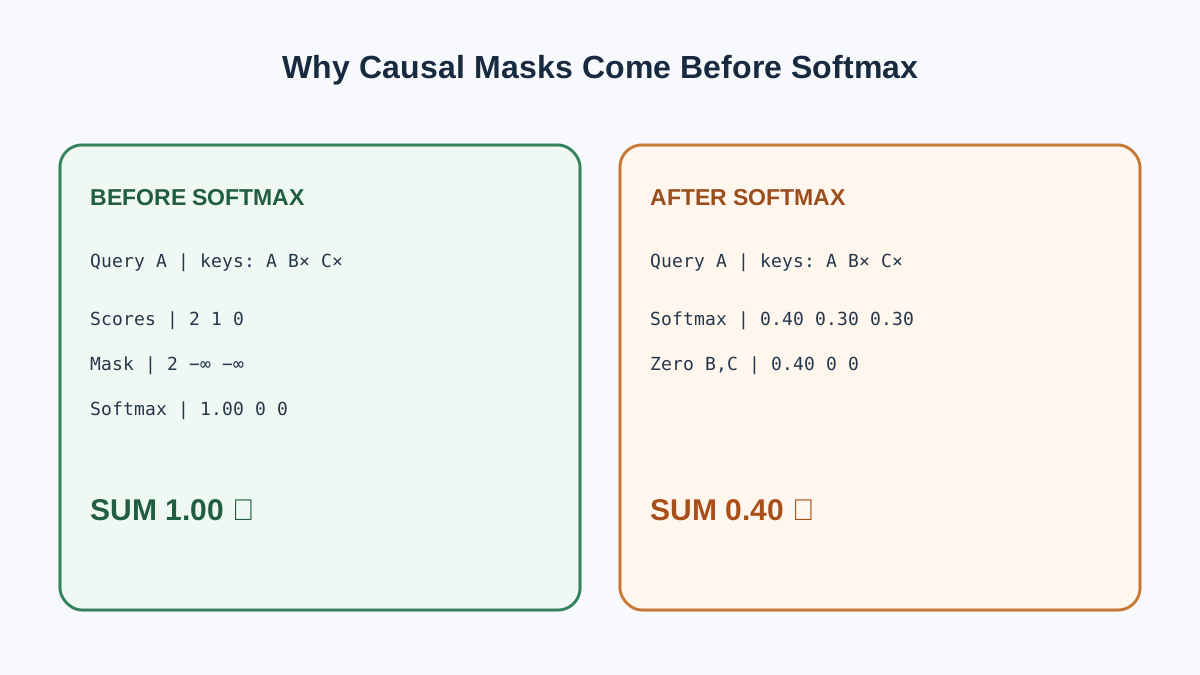
When a model predicts token , the representation for position must not depend on positions after . Otherwise the model could peek at the answer during training.
The mask is an upper-triangular pattern of added to the score matrix before softmax:
Adding this to the scaled scores and then applying softmax gives:
Token A can only attend to itself. Token B attends to A and B. Token C attends to all three — and its row is unchanged from the unmasked matrix, because C is the final position and has no future keys to exclude.
Why before softmax and not after? Because . Softmax of yields exactly zero weight with no special-case code. If you masked after softmax, you would zero out entries that had already been normalized — and the remaining weights would no longer sum to 1.
The diagonal is never masked. A token always attends to itself.
Common mistake: Masking after softmax. The resulting row no longer sums to 1, and your weighted average is no longer an average.
Encoder-style models like BERT use bidirectional attention — no causal mask — because they see the full input at once. Padding masks (which hide filler tokens) combine with causal masks via logical OR: any position masked by either constraint is masked in the combined mask.
Knowledge check
Check your understanding
Answer this question before you continue.
What This Predicts About Real Models
The score matrix is , so attention cost grows quadratically with sequence length. Double the tokens, quadruple the score matrix. This is the mechanical reason long context is expensive — not a policy choice, but arithmetic.
Multi-head attention splits across heads. Each head runs this same computation on a slice, then the outputs are concatenated and mixed with another learned matrix . Different heads can learn to attend to different patterns.
Key/value caching works because of causal masking. Earlier tokens' keys and values do not change when new tokens are appended — they cannot see the future. So during generation, only the newest query needs computing; the keys and values from prior positions are reused.
Where the analogy stops: real models add residual connections, layer normalization, feed-forward blocks, and many stacked layers. One attention head is a component, not the whole model.
Common Mistakes When Tracing Attention by Hand
- Transposing the wrong matrix. is times , producing . Not times .
- Applying softmax to the entire matrix. Softmax is row-wise. Each row is an independent distribution.
- Forgetting the scale factor. Then wondering why one weight is nearly 1.0 and the rest are nearly 0.
- Assuming self-attention is symmetric. It is not. and use different projections, so token 's attention to token need not equal token 's attention to token .
- Masking after softmax. Produces zeros that no longer sum to 1.
- Treating the output as a new token embedding. It is a context-mixed representation that still flows through the rest of the block — layer norm, feed-forward, residual add.
Your Next Step: Change One Number
Reading a derivation is not the same as owning it. Here is the drill that converts one into the other.
Take the worked example and change token B's embedding from to . Before you recompute anything, predict which attention weights will shift. Then do the arithmetic and check.
Next, increase to 4 or 8 and watch how much the raw scores grow. The scaling factor's purpose becomes visible when you see what happens without it.
Finally, remove the causal mask and recompute token A's output. Watch it change. That change is the mask doing real work.
From here, the natural next concepts are multi-head attention and the feed-forward block — or, if you want the practical side, how context length and cost follow directly from that score matrix. Either path builds on what you just traced by hand.
Knowledge check
Final check
Finish the article by checking the ideas you just learned.
References
Want a more structured LLMOps path?
Use the LLMOps Practical Starter Bundle to connect RAG, evaluation, observability, and production patterns.
Large Language Models Starter Pack
A 12-chapter guide connecting LLM fundamentals with prompting, RAG, agents, tool calling, evaluation, security, and application engineering.
- 227-page Illustrated PDF edition
- 12 guided LLM engineering chapters
- Visual concept diagrams
- Self-assessment quizzes
- Bonus deep-dive sections
- Prompt design, structured output, context windows & RAG pipelines
- Agents, tool calling, prompt injection, evaluation & application lifecycles
Coming soon


